AI datasets and VLAI models
Introduction
At CIRCL (Computer Incident Response Center Luxembourg), we often face the challenge of evaluating vulnerabilities with incomplete data—sometimes just a textual description.
To tackle this, we developed an NLP-based model using data from our Vulnerability-Lookup platform. The entire solution is now publicly available, including its integration into our free online service and open-source codebase. With this model, you can generate a VLAI vulnerability severity score even when no official score exists, purely from the description. The model was presented in the paper VLAI: A RoBERTa-Based Model for Automated Vulnerability Severity Classification (arXiv).
What mattered most to us was mastering the full pipeline—from data collection and vulnerability correlation to AI-ready dataset generation, in-house model training, and seamless integration with Vulnerability-Lookup through a dedicated bridge.
We’ll continue to explore new models—always keeping in mind that AI is a tool, not a solution on its own!
Below, we outline the full process behind the VLAI Severity model—a framework that can be adapted to many other use cases.
The full chain
From the raw advisories to an answer in Vulnerability-Lookup or in an AI agent, every step runs on open-source software and, apart from the public sharing on Hugging Face, on our own infrastructure.
  flowchart LR
    SRC["<b>Advisory sources</b><br/>CVE, GHSA, PySec, CSAF,<br/>CNVD, FSTEC, CERT-FR…"]
    VL[("<b>Vulnerability-Lookup</b><br/>feeders, correlation<br/>1M+ JSON records")]
    GEN["<b>VulnTrain</b><br/>dataset generation<br/>leakage-free split"]
    DS[/"<b>Hugging Face</b><br/>open datasets"/]
    TRAIN["<b>VulnTrain</b><br/>training and validation<br/>on our GPUs"]
    MOD[/"<b>Hugging Face</b><br/>open models"/]
    GW["<b>ML-Gateway</b><br/>local inference"]
    API["<b>Vulnerability-Lookup</b><br/>API and web interface"]
    MCP["<b>VulnMCP</b><br/>AI agents"]

    SRC --> VL --> GEN --> DS --> TRAIN --> MOD --> GW
    GW --> API
    GW --> MCP

    classDef open fill:#fff3d6,stroke:#d9a400,color:#000
    class DS,MOD open
- Collect. The feeders of Vulnerability-Lookup gather advisories from many sources and correlate them (a CVE, its GitHub advisory, its vendor errata…).
- Build datasets. VulnTrain turns these records into AI-ready datasets. Records of the same vulnerability are kept on the same side of the train/test split, and an automatic check verifies it.
- Share. Datasets are published openly on Hugging Face, with a dataset card for each version.
- Train and validate. VulnTrain fine-tunes and evaluates the models on our own GPUs, then publishes them, also on Hugging Face.
- Serve. ML-Gateway loads the models locally and answers inference requests, with no data sent to third parties.
- Use. Vulnerability-Lookup exposes the results in its API and web interface, and VulnMCP makes them available to AI agents.
Datasets
We provide several datasets focused on software vulnerabilities. A key resource among them is dedicated to vulnerability scoring, featuring structured CPE data, CVSS scores (across multiple versions), and rich textual descriptions.
Datasets at a glance
| Dataset | Language | Content | Rows | Used for |
|---|---|---|---|---|
| vulnerability-scores | English | CVE, GitHub, PySec and CSAF advisories with their CVSS scores and CPEs | 837,209 | Severity classification |
| Vulnerability-CNVD | Chinese | CNVD vulnerabilities with their severity | 129,857 | Severity classification |
| Vulnerability-FSTEC | Russian | FSTEC/BDU vulnerabilities with their CVSS scores | 98,523 | Severity classification |
| Vulnerability-CERT-FR | French | CERT-FR alerts and advisories, labelled from the CVEs they reference | 10,435 | Severity classification |
| vulnerability-attack-techniques | English | CVEs with expert MITRE ATT&CK technique mappings | 1,207 | ATT&CK technique suggestion |
| vulnerability-cwe-patch | English | Vulnerabilities with their CWE, commit messages and patches | 1,743 | CWE classification |
| vulnerability | English | Vulnerability descriptions | 573,181 | Description generation |
All datasets are generated with VulnTrain from the data of Vulnerability-Lookup.
Vulnerabilities with CVSS scores
This dataset aggregates vulnerabilities from multiple sources, including:
- cvelistv5
- github
- csaf_redhat
- csaf_cisco
- csaf_cisa
- pysec
Each vulnerability entry includes a source field identifying its origin, making it easier to trace and filter data.
This dataset is updated daily.
Sources of the data:
- CVE Program (enriched with data from vulnrichment and Fraunhofer FKIE)
- GitHub Security Advisories
- PySec advisories
- CSAF Red Hat
- CSAF Cisco
- CSAF CISA
The licenses for each security advisory feed are listed here:
https://vulnerability.circl.lu/about#sources
This represents more than 830,000 advisories available via the interface of Vulnerability-Lookup.
The dataset has three splits: train, validation and test (80/10/10). Records that describe the same vulnerability—for example a CVE and its GitHub advisory, which often share the same description—are always kept in the same split, so that models are evaluated on vulnerabilities they have never seen. CVSS 4.0 scores are read with base metrics only (CVSS-B), whatever the source.
See the technical report Improving vulnerability-scores: Leakage-Free Splits and Consistent CVSS 4.0 Scoring for details.
Get started with the dataset:
import json
from datasets import load_dataset

dataset = load_dataset("CIRCL/vulnerability-scores")

vulnerabilities = ["CVE-2012-2339", "RHSA-2023:5964", "GHSA-7chm-34j8-4f22", "PYSEC-2024-225"]

filtered_entries = dataset.filter(lambda elem: elem["id"] in vulnerabilities)

for split in filtered_entries:
    for entry in filtered_entries[split]:
        print(split, json.dumps(entry, indent=4))
For each vulnerability, you will find all assigned severity scores and associated CPEs.
CNVD vulnerabilities
A separate dataset focuses on CNVD (China National Vulnerability Database) vulnerabilities, with descriptions in Chinese.
Browse the dataset
The dataset includes a cve_id field cross-referencing CVE equivalents (~81% of entries). The ~19% of CNVD-only entries are concentrated in Chinese domestic software. See the dataset card for details on severity distribution, CVE overlap, and the post-2021 coverage decline following China’s RMSV regulations.
FSTEC vulnerabilities
A dataset of vulnerabilities from the Russian Federal Service for Technical and Export Control (FSTEC/BDU), with descriptions in Russian.
Browse the dataset
CVSS base scores are parsed from vector strings (v2.0, v3.0, v4.0). CVE cross-references are included when available. Each entry includes a source field identifying its origin.
CERT-FR bulletins
A dataset of security bulletins in French published by CERT-FR: alerts (certfr_alerte) and advisories (certfr_avis), including the earlier CERTA bulletins.
Browse the dataset
CERT-FR bulletins do not carry a severity rating of their own, so each bulletin is labelled with the CVSS scores of the CVEs it references, the highest score (cvss_max) being the recommended label. Only bulletins referencing between 1 and 10 CVEs are kept, as larger bulletins are usually vendor patch roll-ups. The dataset contains about 10,400 bulletins. See the dataset card for the labelling rules, the severity distribution and how to handle bulletins scored only with CVSS v2.0.
Models
Models at a glance
| Model | Task | Language | Base model | Evaluation | Result |
|---|---|---|---|---|---|
| vulnerability-severity-classification-roberta-base | Severity (Low, Medium, High, Critical) | English | roberta-base | Leakage-free test split | 74.2% accuracy |
| vulnerability-severity-classification-chinese-macbert-base | Severity (低, 中, 高) | Chinese | chinese-macbert-base | Test split deduplicated on description | 76.2% accuracy |
| vulnerability-severity-classification-russian-ruRoberta-large | Severity (Low, Medium, High, Critical) | Russian | ruRoberta-large | Leakage-free test split | 70.0% accuracy |
| cwe-parent-vulnerability-classification-roberta-base | Parent CWE | English | roberta-base | Test split | 56.8% accuracy |
| vulnerability-attack-technique-classification-roberta-base | MITRE ATT&CK techniques (53, multi-label) | English | roberta-base | Held-out test split | 64% recall@5 |
| vulnerability-attack-technique-biencoder | MITRE ATT&CK technique ranking (open vocabulary) | English | roberta-base | Five seeds | 64% recall@5 |
| vulnerability-description-generation-gpt2-xl | Description writing assistance | English | gpt2-xl | – | – |
Each model card on Hugging Face gives the training data, the per-class results and the limitations of the model.
How We Build Our VLAI Models
With the various vulnerability feeders of Vulnerability-Lookup (for the CVE Program, NVD, Fraunhofer FKIE, GHSA, PySec, CSAF sources, Japan Vulnerability Database, etc.) we’ve collected over a million JSON records. This allows us to generate the dataset previously presented for training and building models.
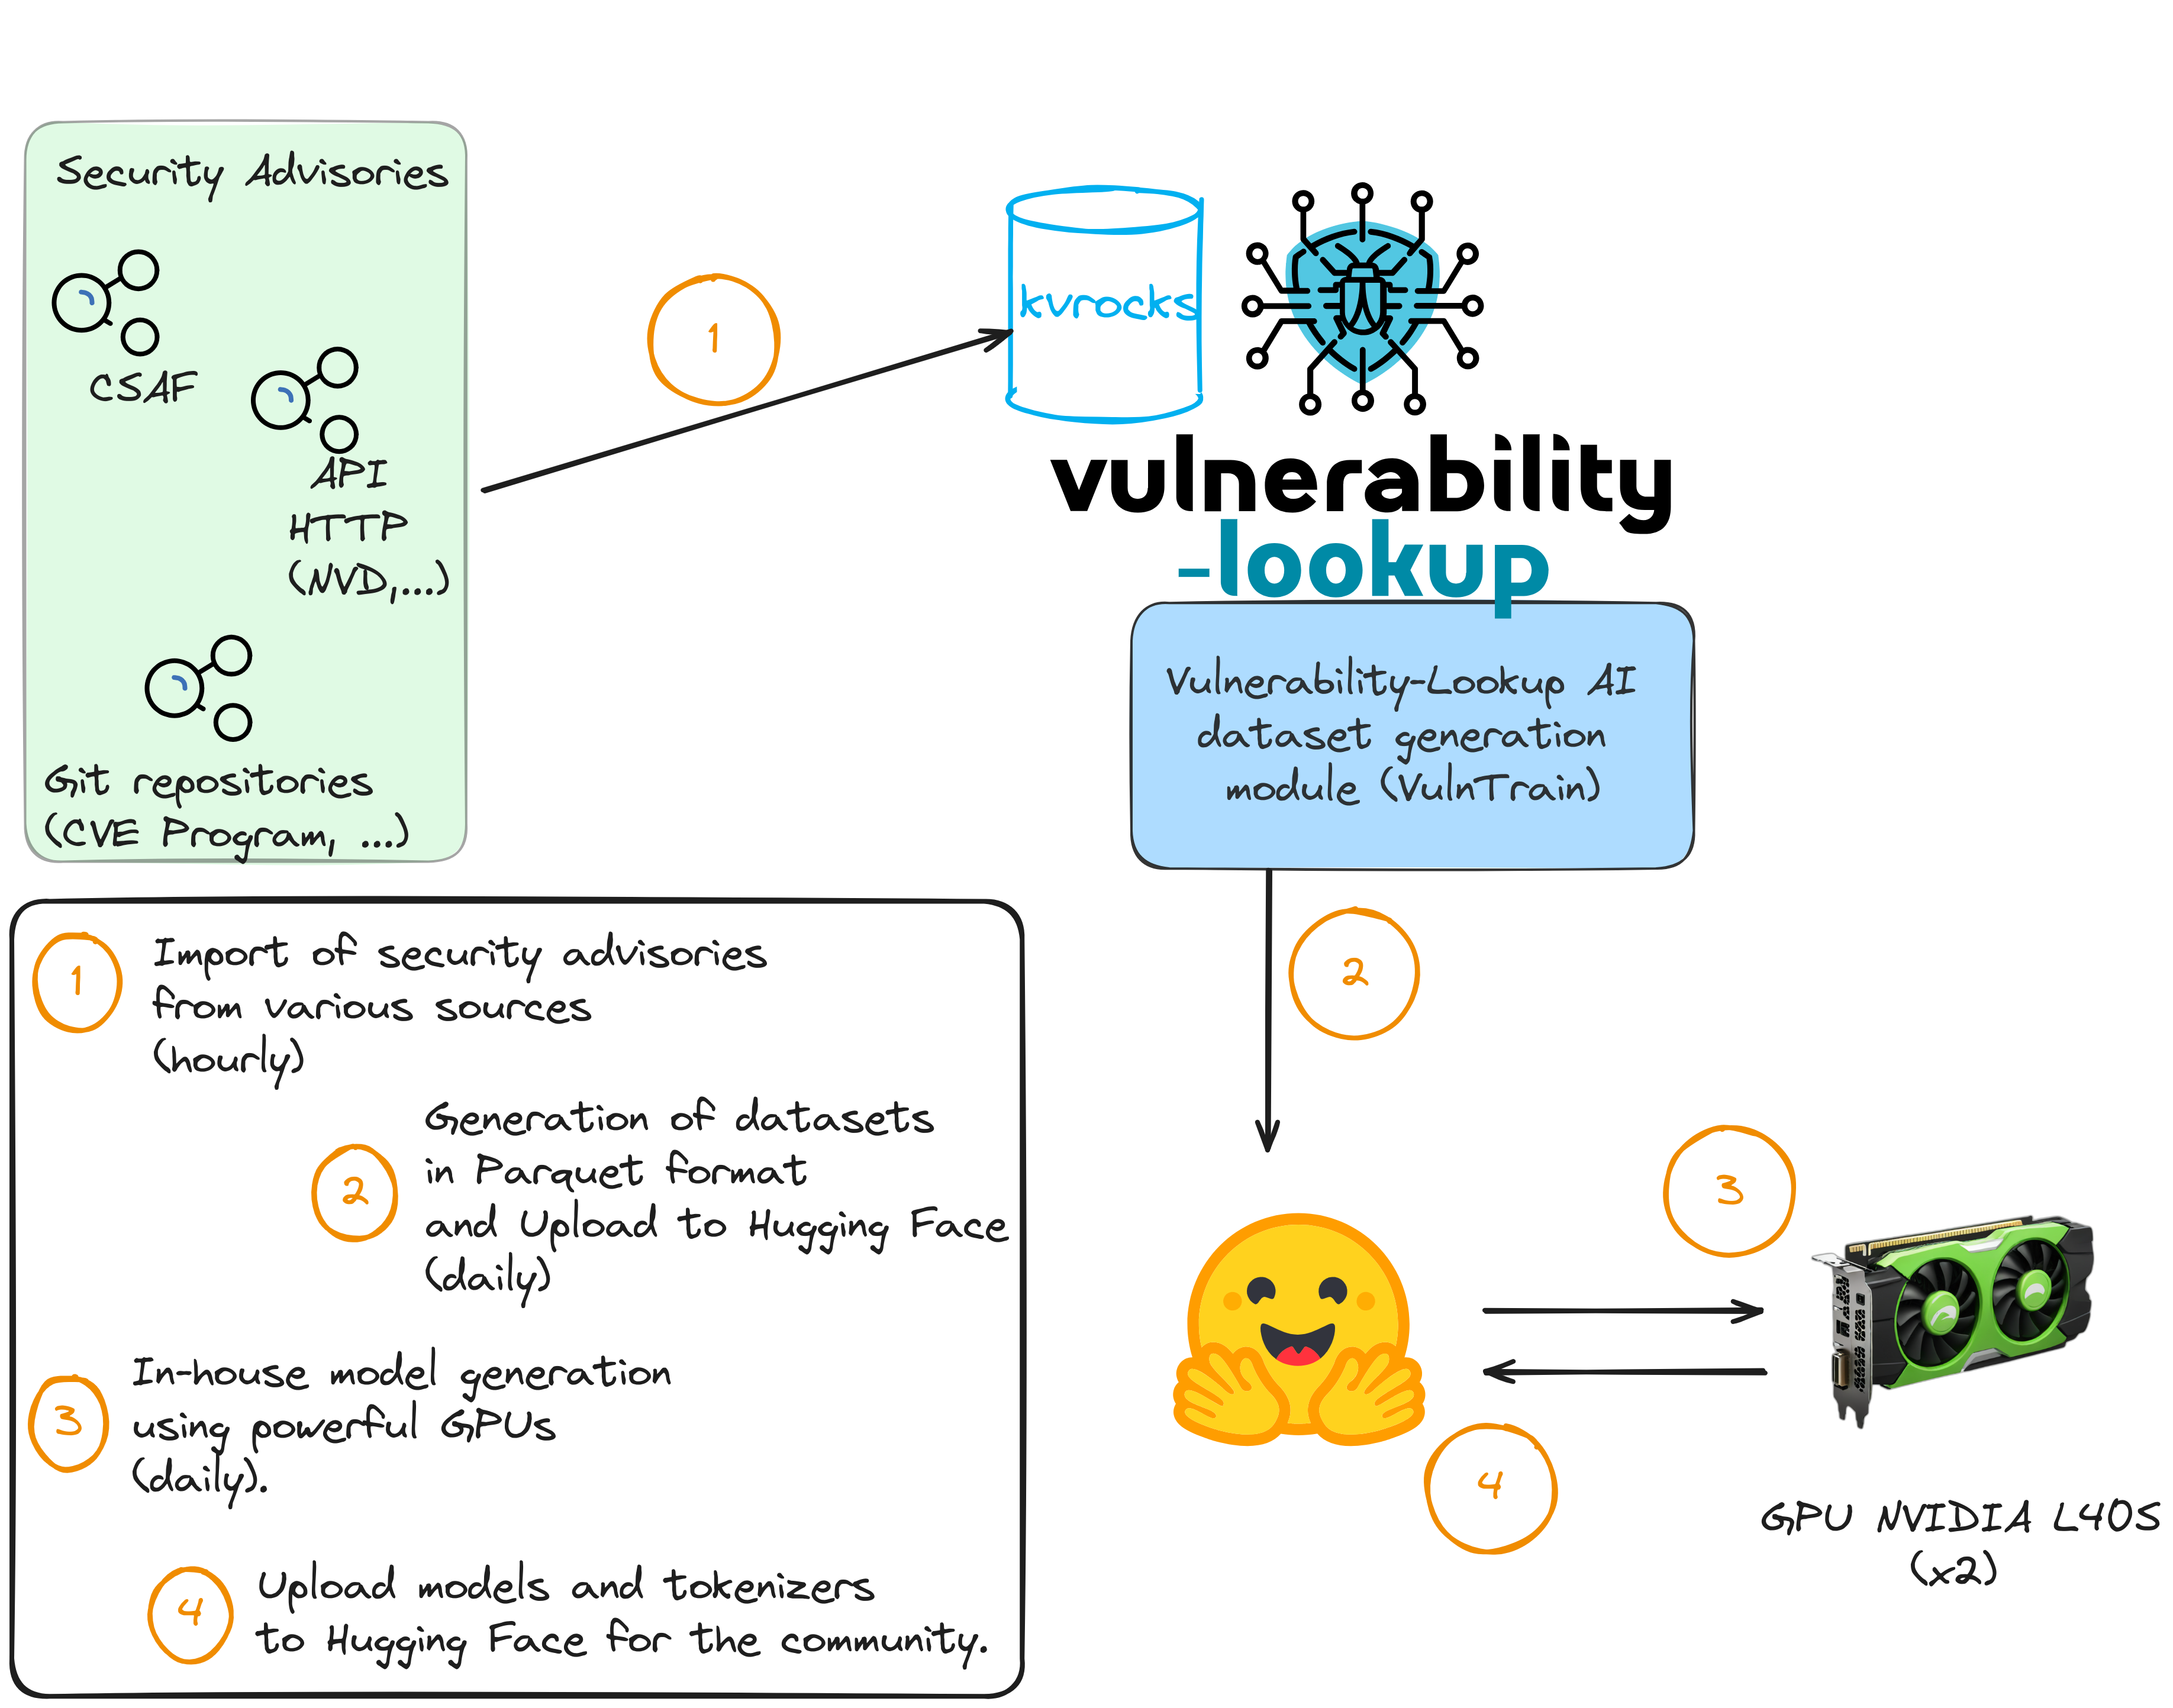
In this diagram, the AI dataset is generated (step 2) by a dedicated project: VulnTrain. This software is easy to install and usable via the command line. It provides three main capabilities:
- Dataset generation – Create and prepare datasets from multiple sources (CVE, GitHub, CSAF, PySec, CNVD, FSTEC, CERT-FR). When generating a dataset from multiple sources, a dataset card is automatically created with a per-source breakdown table showing entry counts and percentages.
- Model training – Train models using the prepared datasets.
- Train a model to classify vulnerabilities by severity (English, Chinese, Russian).
- Train a model to classify CWEs from vulnerability descriptions and patches.
- Train models to suggest MITRE ATT&CK techniques from vulnerability descriptions.
- Train a model for text generation to assist in writing vulnerability descriptions.
- Model validation – Assess and compare the performance of trained models. The severity trainer reports precision, recall, and F1 per class (Low / Medium / High / Critical) alongside overall accuracy and macro F1.
Models are generated using our own GPUs and our open-source trainers. Like the datasets, model updates are performed regularly.
Text classification model
vulnerability-severity-classification-roberta-base
This model is a fine-tuned version of FacebookAI/roberta-base trained on the CIRCL/vulnerability-scores dataset.
| Dataset | CIRCL/vulnerability-scores |
| Model | CIRCL/vulnerability-severity-classification-roberta-base |
| Base model | FacebookAI/roberta-base |
The model classifies 74% of vulnerabilities correctly across the four severity classes (Low, Medium, High, Critical), measured on the leakage-free test split, that is on vulnerabilities it has never seen during training. See the model card for the per-class results.
Training with 4 NVIDIA L40S GPUs takes about 4.5 hours.
Try it with Python:
from transformers import AutoModelForSequenceClassification, AutoTokenizer
import torch

model_name = "CIRCL/vulnerability-severity-classification-roberta-base"
# The models are retrained regularly: pin a revision for reproducible results.
revision = "064daa2"
tokenizer = AutoTokenizer.from_pretrained(model_name, revision=revision)
model = AutoModelForSequenceClassification.from_pretrained(model_name, revision=revision)
model.eval()

test_description = "langchain_experimental 0.0.14 allows an attacker to bypass the CVE-2023-36258 fix and execute arbitrary code via the PALChain in the python exec method."
inputs = tokenizer(test_description, return_tensors="pt", truncation=True, padding=True)

# Run inference
with torch.no_grad():
    outputs = model(**inputs)
    predictions = torch.nn.functional.softmax(outputs.logits, dim=-1)

# Print results
print("Predictions:", predictions)
predicted_class = torch.argmax(predictions, dim=-1).item()
print("Predicted severity:", model.config.id2label[predicted_class])
Example output:
Predictions: tensor([[0.0019, 0.0386, 0.3563, 0.6032]])
Predicted severity: Critical
vulnerability-severity-classification-chinese-macbert-base
This model is a fine-tuned version of hfl/chinese-macbert-base trained on the CIRCL/Vulnerability-CNVD dataset. It classifies severity of vulnerabilities based on Chinese descriptions into three levels: 低 (Low), 中 (Medium), and 高 (High).
| Dataset | CIRCL/Vulnerability-CNVD |
| Model | CIRCL/vulnerability-severity-classification-chinese-macbert-base |
| Base model | hfl/chinese-macbert-base |
The model achieves 76.2% accuracy on a test set deduplicated on description text. Known limitations include low recall on the Low severity class (~41%) and keyword dependency. See the model card and improvements report for details.
vulnerability-severity-classification-russian-ruRoberta-large
This model is a fine-tuned version of ai-forever/ruRoberta-large trained on the CIRCL/Vulnerability-FSTEC dataset. It classifies severity of vulnerabilities based on Russian descriptions from the FSTEC/BDU database.
| Dataset | CIRCL/Vulnerability-FSTEC |
| Model | CIRCL/vulnerability-severity-classification-russian-ruRoberta-large |
| Base model | ai-forever/ruRoberta-large |
It uses four labels: Low, Medium, High, and Critical (derived from CVSS scores).
The model achieves 70.0% accuracy on a leakage-free test split. Since November 2026 its labels come from the CVSS 4.0 and 3.x scores of the BDU records as well as CVSS 2.0; before, only CVSS 2.0 scores were read, so the earlier 74.2% is not comparable. Low remains the weakest class (recall ~19%). See the model card for details.
CWE classification model
cwe-parent-vulnerability-classification-roberta-base
This model predicts the parent CWE category of a vulnerability from its description, together with the commit messages and patches when they are available. It is trained on the CIRCL/vulnerability-cwe-patch dataset and is available to AI agents through VulnMCP.
| Dataset | CIRCL/vulnerability-cwe-patch |
| Model | CIRCL/cwe-parent-vulnerability-classification-roberta-base |
| Base model | FacebookAI/roberta-base |
MITRE ATT&CK technique suggestion
Two models suggest MITRE ATT&CK (Enterprise) techniques from a vulnerability description, for review by an analyst. Both are trained on CIRCL/vulnerability-attack-techniques, a curated set of about 1,200 CVEs whose labels come from expert MITRE CTID mappings.
- vulnerability-attack-technique-classification-roberta-base scores 53 parent techniques. On average, 64% of the techniques chosen by experts for an unseen CVE appear in its top five suggestions.
- vulnerability-attack-technique-biencoder compares the description with the official ATT&CK technique descriptions, so it can rank any of the 222 active parent techniques, including rare ones.
The suggestions are shown in the ATT&CK tab of every vulnerability page of Vulnerability-Lookup (example: CVE-2021-44077). The methodology and the evaluation are described in the paper Mapping CVEs to MITRE ATT&CK Techniques: A Curated Gold-Set Classifier and the Limits of LLM-Assisted Label Expansion.
Text generation model
vulnerability-description-generation-gpt2-xl
A fine-tuned version of gpt2-xl trained on the CIRCL/vulnerability dataset, to assist in writing vulnerability descriptions. See the model card for an example.
Putting Our Models to Work in Vulnerability-Lookup
VLAI in the web interface
Every vulnerability page of Vulnerability-Lookup shows a VLAI badge next to the EPSS score: the severity estimated by our models from the description of the vulnerability, with the confidence of the prediction. The model is chosen according to the language of the description (English, Chinese or Russian). The VLAI severity is computed even when an official CVSS score exists, so both can be compared; it is most useful when there is none.
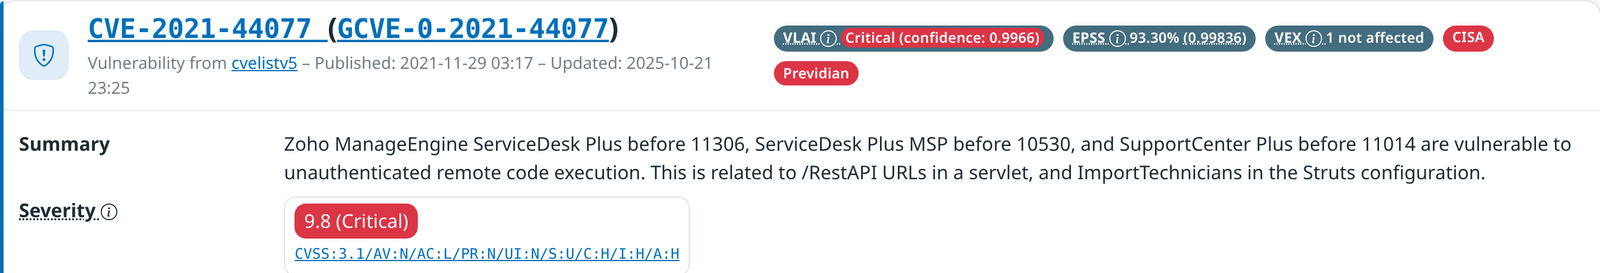
The ATT&CK tab of the same page lists the MITRE ATT&CK techniques suggested by our ATT&CK models.
ML-Gateway
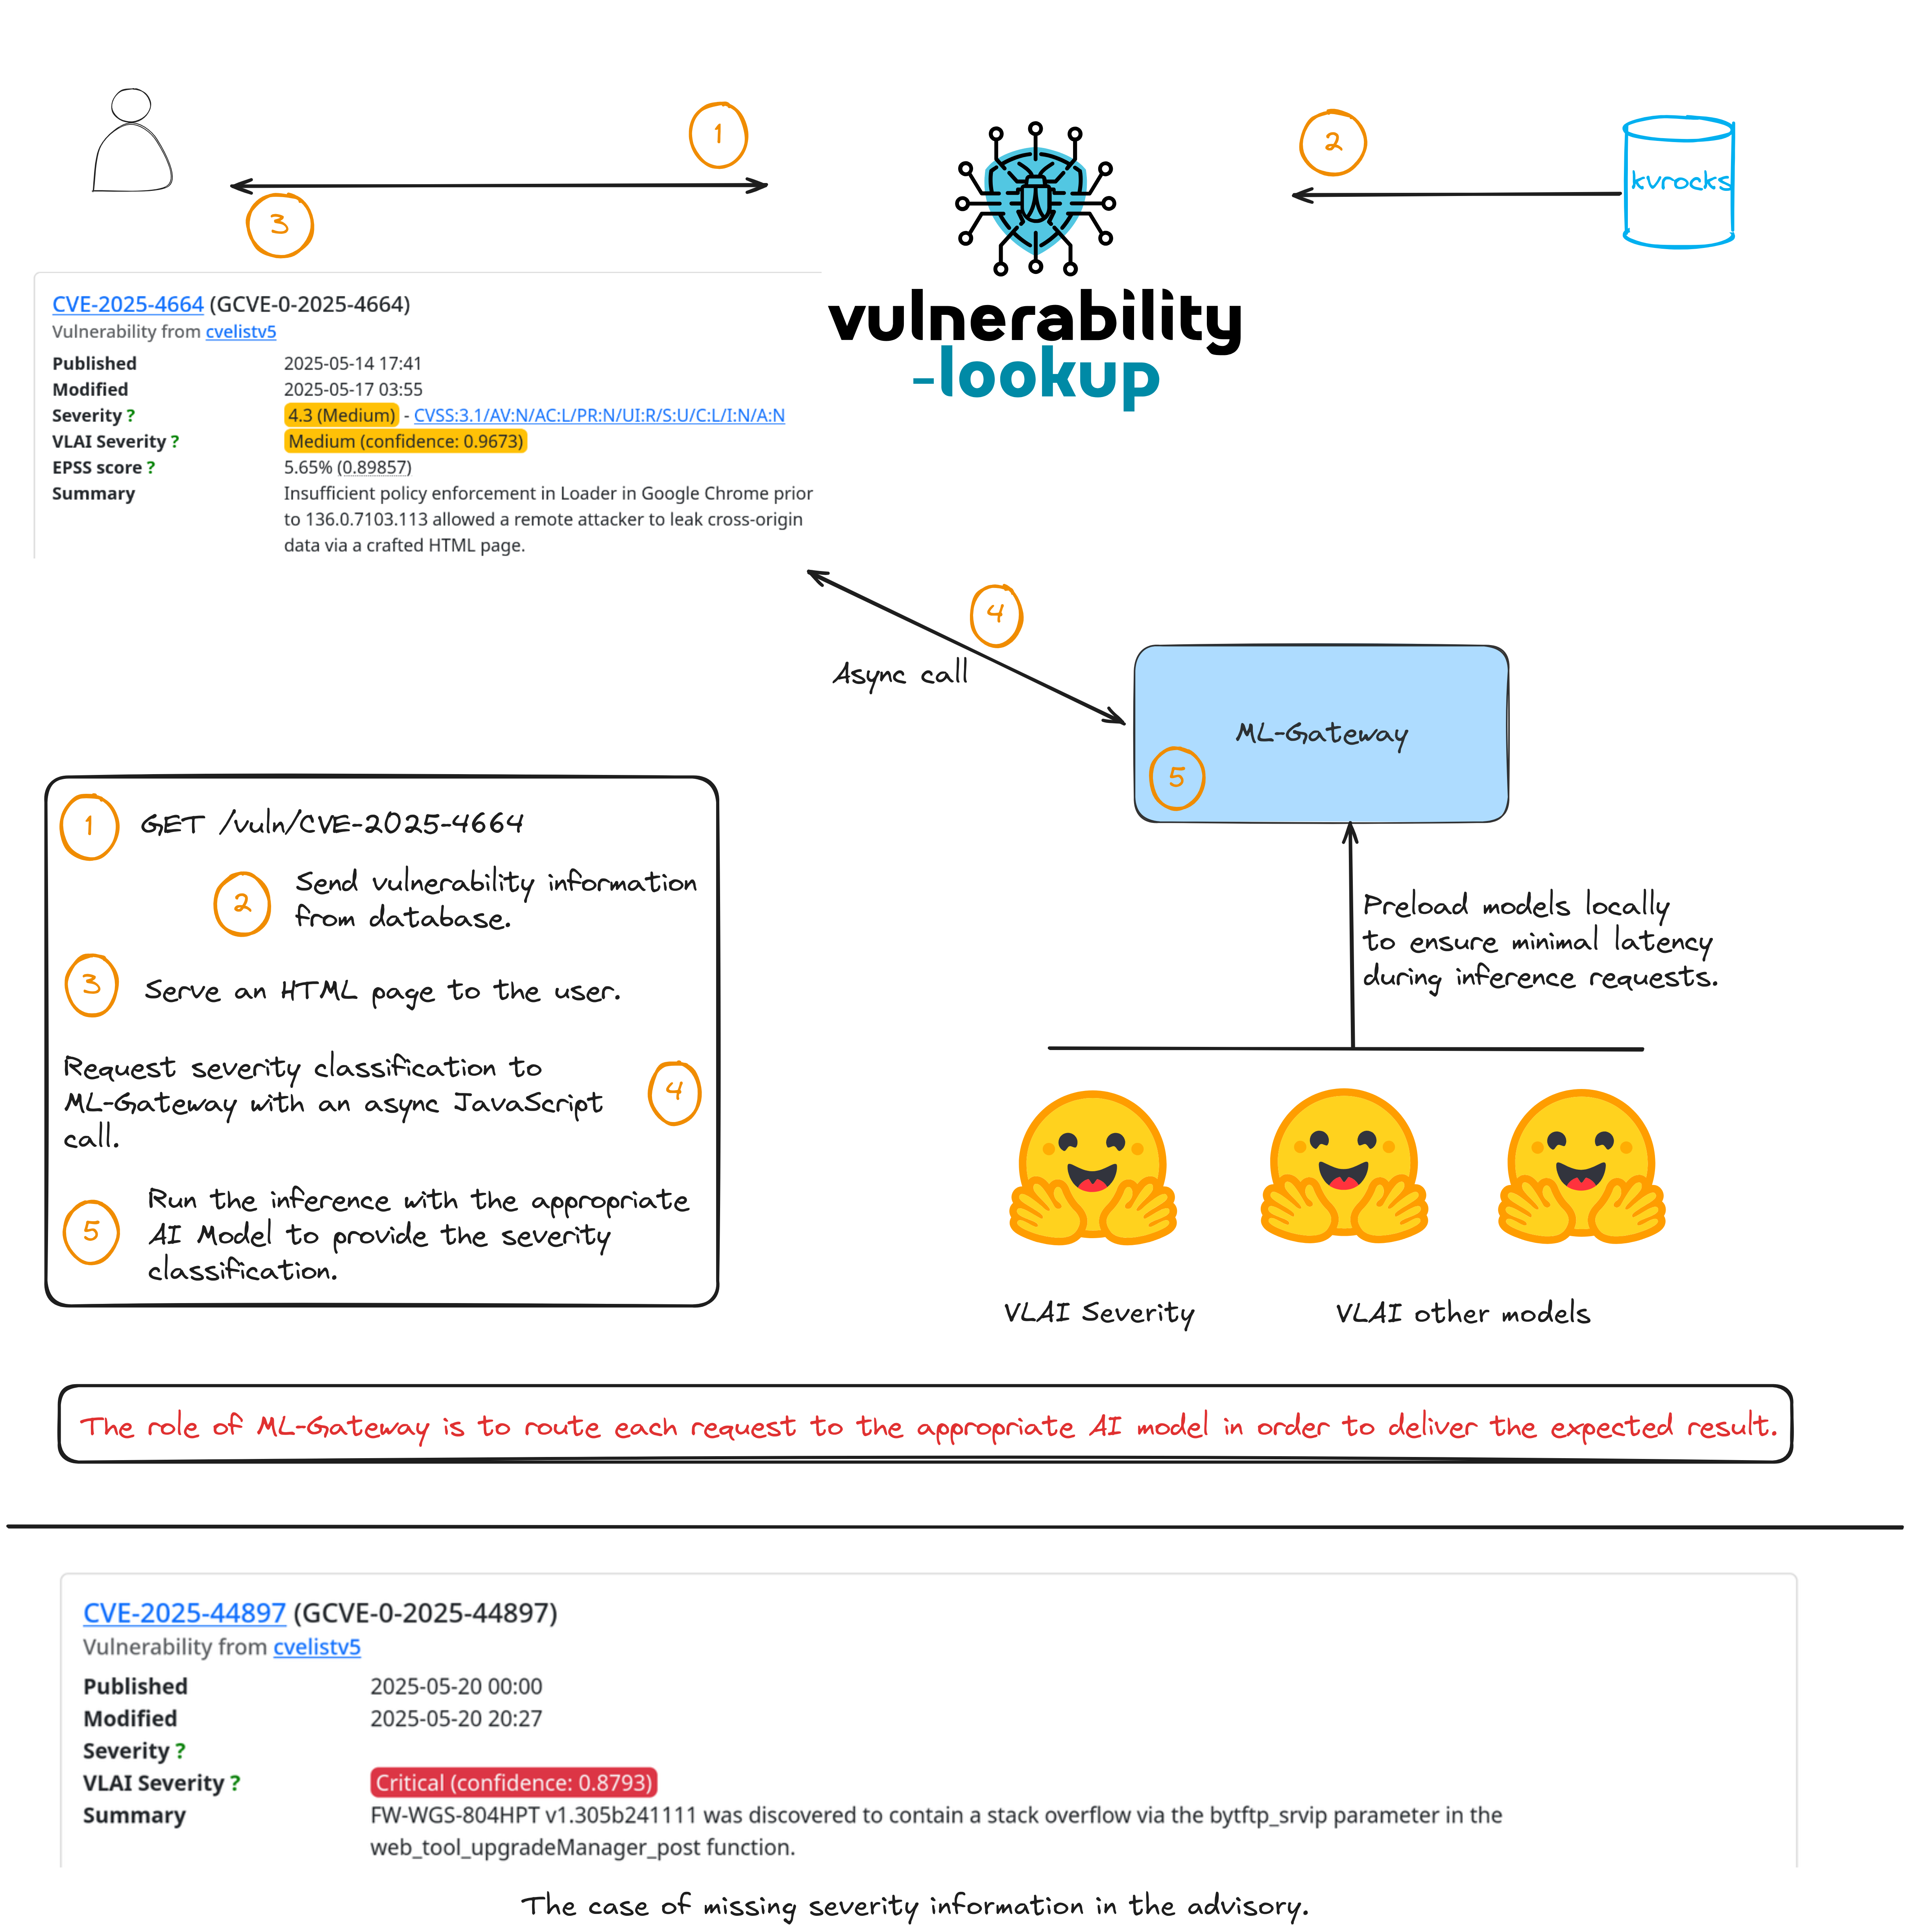
ML-Gateway is a FastAPI-based local server that loads pre-trained NLP models at startup and exposes them via a RESTful API for inference. It supports multilingual severity classification out of the box: clients simply specify the desired model in their request.
Models are loaded locally via ML-Gateway to ensure minimal latency. All inference and processing are performed on our servers—no data is sent to Hugging Face. We use the Hugging Face platform to share our datasets and models publicly, reinforcing our commitment to open collaboration.
Think of it as a lightweight model-serving layer that allows us to integrate multiple AI models without adding complexity to Vulnerability-Lookup.
Each model is accessible via dedicated HTTP endpoints. OpenAPI documentation is automatically generated and describes all available endpoints, input formats, and example responses—making integration straightforward. The /vlai/severity-classification API endpoint of Vulnerability-Lookup is relying on the API of ML-Gateway. It requires authentication, for example with the API key of your Vulnerability-Lookup account:
$ curl -X 'POST' \
  'https://vulnerability.circl.lu/api/vlai/severity-classification' \
  -H 'accept: application/json' \
  -H 'Content-Type: application/json' \
  -H 'X-API-KEY: <your API key>' \
  -d '{
  "description": "An authentication bypass in the API component of Ivanti Endpoint Manager Mobile 12.5.0.0 and prior allows attackers to access protected resources without proper credentials via the API."
}'
{"severity": "High", "confidence": 0.6008}
The Vulnerability-Lookup backend simply forwards the request to the corresponding ML-Gateway endpoint and returns the result to the client. In our case the gateway is not directly accessible from the Web.
Ultimately, our goal is to enhance vulnerability data descriptions using a growing suite of NLP models, directly supporting Vulnerability-Lookup and related services.
Exposing Models to AI Agents with VulnMCP
VulnMCP is an MCP server built with FastMCP that exposes our VLAI models—and the broader Vulnerability-Lookup ecosystem—to AI clients, chat agents, and other automated systems via the Model Context Protocol.
Where ML-Gateway serves models through a REST API for programmatic use, VulnMCP makes them available as modular tools that any MCP-compatible AI agent (such as Claude Code or Claude Desktop) can invoke directly during a conversation.
Key capabilities
- Vulnerability Severity Classification – Classify vulnerability severity (Low / Medium / High / Critical) from a text description using CIRCL’s fine-tuned NLP models. Supports English, Chinese, and Russian with automatic language detection.
- CWE Classification – Predict CWE categories from vulnerability descriptions using CIRCL/cwe-parent-vulnerability-classification-roberta-base.
- Vulnerability Lookup – Query the Vulnerability-Lookup API to get detailed information about specific CVEs, search vulnerabilities by source, CWE, product, or date, find community comments, and discover curated vulnerability bundles.
- KEV Catalog – Browse and filter Known Exploited Vulnerability (KEV) entries, check whether a CVE appears in a KEV catalog, and filter by catalog origin (CISA KEV, CIRCL, EUVD KEV).
- GCVE Registry – Query the GCVE Global Numbering Authority (GNA) registry and references.
Quick start
Requires Python 3.10+ and Poetry v2+.
git clone https://github.com/vulnerability-lookup/VulnMCP.git
cd VulnMCP
poetry install
Register VulnMCP as an MCP server in Claude Code:
claude mcp add vulnmcp -- poetry --directory /path/to/VulnMCP run vulnmcpOnce registered, all tools are available to the AI agent. For example, to classify severity from a description:
poetry run fastmcp call vulnmcp/server.py classify_severity \
    description="A remote code execution vulnerability allows an attacker to execute arbitrary code via a crafted JNDI lookup."
Publications
- Bonhomme, C., & Dulaunoy, A. (2025). VLAI: A RoBERTa-Based Model for Automated Vulnerability Severity Classification. arXiv:2507.03607. https://arxiv.org/abs/2507.03607
- Bonhomme, C. (2025). GPU Efficiency in VLAI Model Training: Experiences and Benchmarks from Months of VLAI Vulnerability Severity Classification Model Training. Technical report, CIRCL. doi:10.13140/RG.2.2.24233.04963
- Bonhomme, C., & Dulaunoy, A. (2026). Mapping CVEs to MITRE ATT&CK Techniques: A Curated Gold-Set Classifier and the Limits of LLM-Assisted Label Expansion. arXiv:2607.25572. https://arxiv.org/abs/2607.25572
- Bonhomme, C. (2026). Improving vulnerability-scores: Leakage-Free Splits and Consistent CVSS 4.0 Scoring. Technical report, CIRCL. doi:10.5281/zenodo.23760802
- CNVD severity classification improvements (VulnTrain documentation)
Funding
The VLAI datasets and models are developed at CIRCL in the context of the AIPITCH project, co-funded by the European Union.